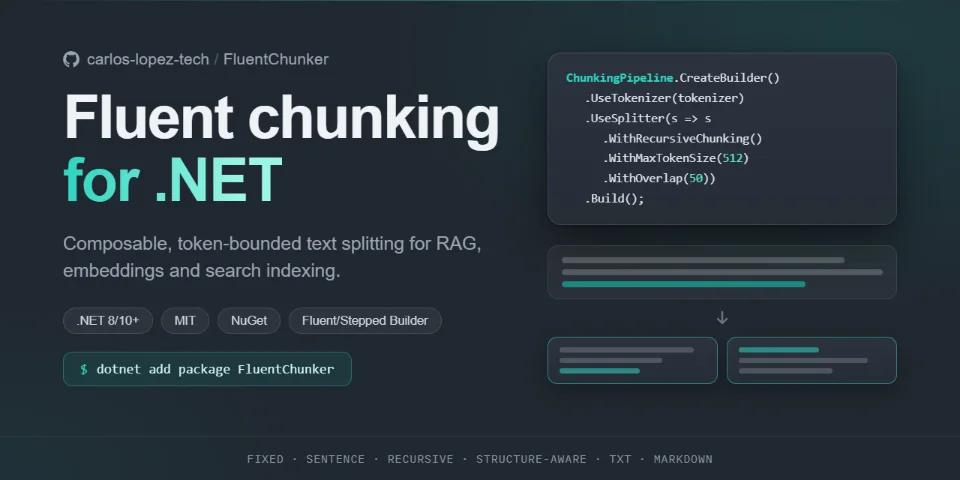
Fluent Chunker is a flexible text-chunking library for modern LLM and RAG applications, designed to provide precise control over how documents are segmented and prepared for embedding generation, semantic search, and retrieval.
Built around a stepped builder API, it enables expressive, chain-based pipeline configuration with compile-time-enforced step ordering. It offers four chunking strategies: fixed-size, sentence-aware, recursive, and Markdown structure-aware chunking. All strategies feature accurate, tokenizer-based token counting to ensure chunks never exceed their configured token limits.
Additional capabilities include support for multiple embedding-model tokenizers, configurable token overlap, source offsets, and flexible metadata handling. Its streaming API enables efficient document processing with cancellation support and reusable pipeline configurations.